One-take 30-second clips
Generate up to 30 seconds in a single native pass, with no stitching. A full ad spot or scene plays out end to end, and can be extended when you need more.
Create full 30-second scenes from a prompt, an image, or your own references. ByteDance's newest video model delivers cinematic motion, native audio, and consistent characters in a single take.
Generate up to 30 seconds in a single native pass, with no stitching. A full ad spot or scene plays out end to end, and can be extended when you need more.
Guide a generation with as many as 50 mixed references. Lock your character, set, wardrobe, and palette before the first frame is ever rendered.
Dialogue, sound effects, and music are generated together with the picture instead of layered afterwards, so timing, lip-sync, and ambience land on the first try.
Describe camera moves, pacing, and cuts in plain language. Adjust a region or swap a background without regenerating the entire clip.
Start creating with ByteDance Seedance 2.5 by following a few simple steps directly inside the DaVinci AI Toolkit.
Seedance 2.5 by ByteDance supports creators who need longer, reference-accurate video without cutting several short clips together.
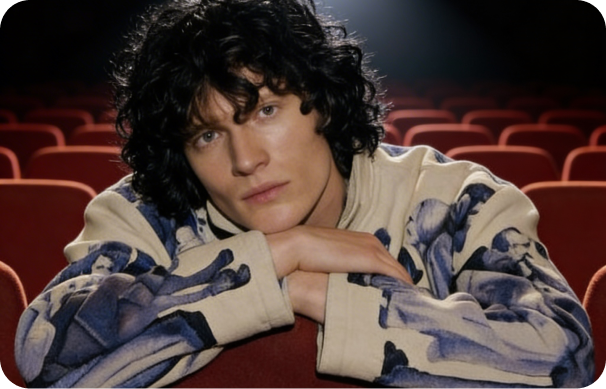
Produce short-form videos, reels, and skits that run long enough for a real story beat, with lifelike motion, consistent characters, and audio built in.
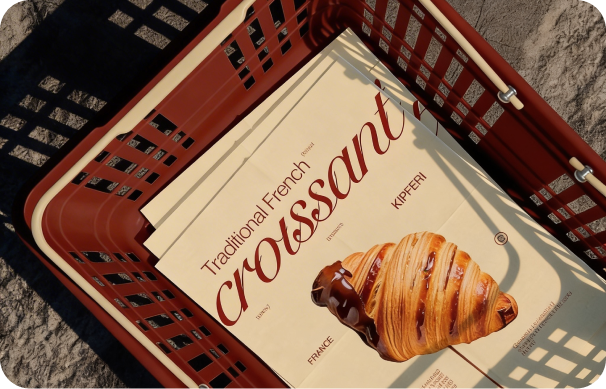
Cover a complete 30-second spot in one generation, then localize it with native support for 10+ languages. Test more concepts in less time and at lower production cost.
Previsualize sequences, explore story concepts, and keep continuity across shots by feeding the model your existing character, set, and style references.
Produce short-form videos, reels, and skits that run long enough for a real story beat, with lifelike motion, consistent characters, and audio built in.
Cover a complete 30-second spot in one generation, then localize it with native support for 10+ languages. Test more concepts in less time and at lower production cost.
Previsualize sequences, explore story concepts, and keep continuity across shots by feeding the model your existing character, set, and style references.
Enter a text prompt or upload your references, and generate a cinematic, audio-synced video with Seedance 2.5 in just seconds.
Seedance 2.5 AI combines long single takes, deep reference control, and native audio to deliver finished scenes from a prompt, an image, or your own footage.
Start from a text prompt, animate a single image, or build a shot from a full reference set. The same model handles all three.
Combine up to 30 images, 10 video clips, and 10 audio tracks in one generation, then point to any of them directly inside your prompt.
Add a voice, music, or sound-effect track and let it drive the pacing, beat-matching, and lip-sync of the entire shot on its own.
Swap a background, adjust a single region, or extend a finished clip while keeping the look, characters, and lighting you already locked in.